AI, Graphics, and Doodling.
I am a Senior Staff Research Engineer at Meta Reality Labs, working on real-time graphics and visual computing. This site keeps growing the same three things: models run and probed on machines you can point at, renderers written to find out how light actually reaches a pixel, and a crayon-doodle shelf of bedtime picture books drawn to a four-year-old's specifications.
Latest writing
All 23 pieces →-
You Get What You Pay For, Plus Extra Yellow
Genuine toner cost five times as much, so I bought third-party, and every print came out yellow. I put a color-correcting print queue in front of the printer and calibrated it with the printer's own scanner, until the printer moved under me at midnight. What fixed it in the end, and why a picture book outranked the scanner.
Nov 1, 2026
-
I Got Tired of Checking My Token Quota, So I Made It Impossible Not to See
I kept stopping mid-task to check how much Codex and Claude quota I had left. Quota Float is a small macOS floating panel and menu-bar gauge that keeps those numbers on screen all the time, read through the signed-in CLIs without touching any credentials.
Oct 27, 2026
-
Wukong & Friends, Updated: Nine Bilingual Books and a Download Button I Deleted
Three days after introducing the bedtime story site: five books became nine, the books themselves went bilingual, every title ships four PDFs instead of two, the licence moved inside the files, and the download countdown is gone. What changed, and why.
Oct 23, 2026
-
The Better Model That Wouldn't Fit: Qwen 3.8 27B on a 32 GB Arc Pro B70
Qwen 3.8 27B is a clearly better model than the MoE I run today, and one 32 GB Arc Pro B70 will not hold it at a context length worth having. What 'too heavy' actually decomposes into — weights, KV cache, drafter, and cold prefill — measured from 64K to 220K, the speculative-decoding break-even curve that grows from 43 tokens to 2,361, and why the port went back to a MoE.
Oct 22, 2026
-
My Qwen 3.8 Flash Next on Strata Got 40% Slower Overnight, and It Wasn't the GPU
My Qwen 3.8 Flash Next on Strata, running on an Intel Arc Pro B70, fell from 42 tok/s to 26 tok/s with no config change. The cause was a pinned-memory mirror of MoE experts being allocated while Linux reclaimed page cache — pages the GPU reads at 55–85% speed while the CPU reads the same pages at full speed. What the measurements looked like, why my first three diagnoses were all wrong, and the 45-line patch that went upstream.
Oct 22, 2026
Selected work
All projects →-
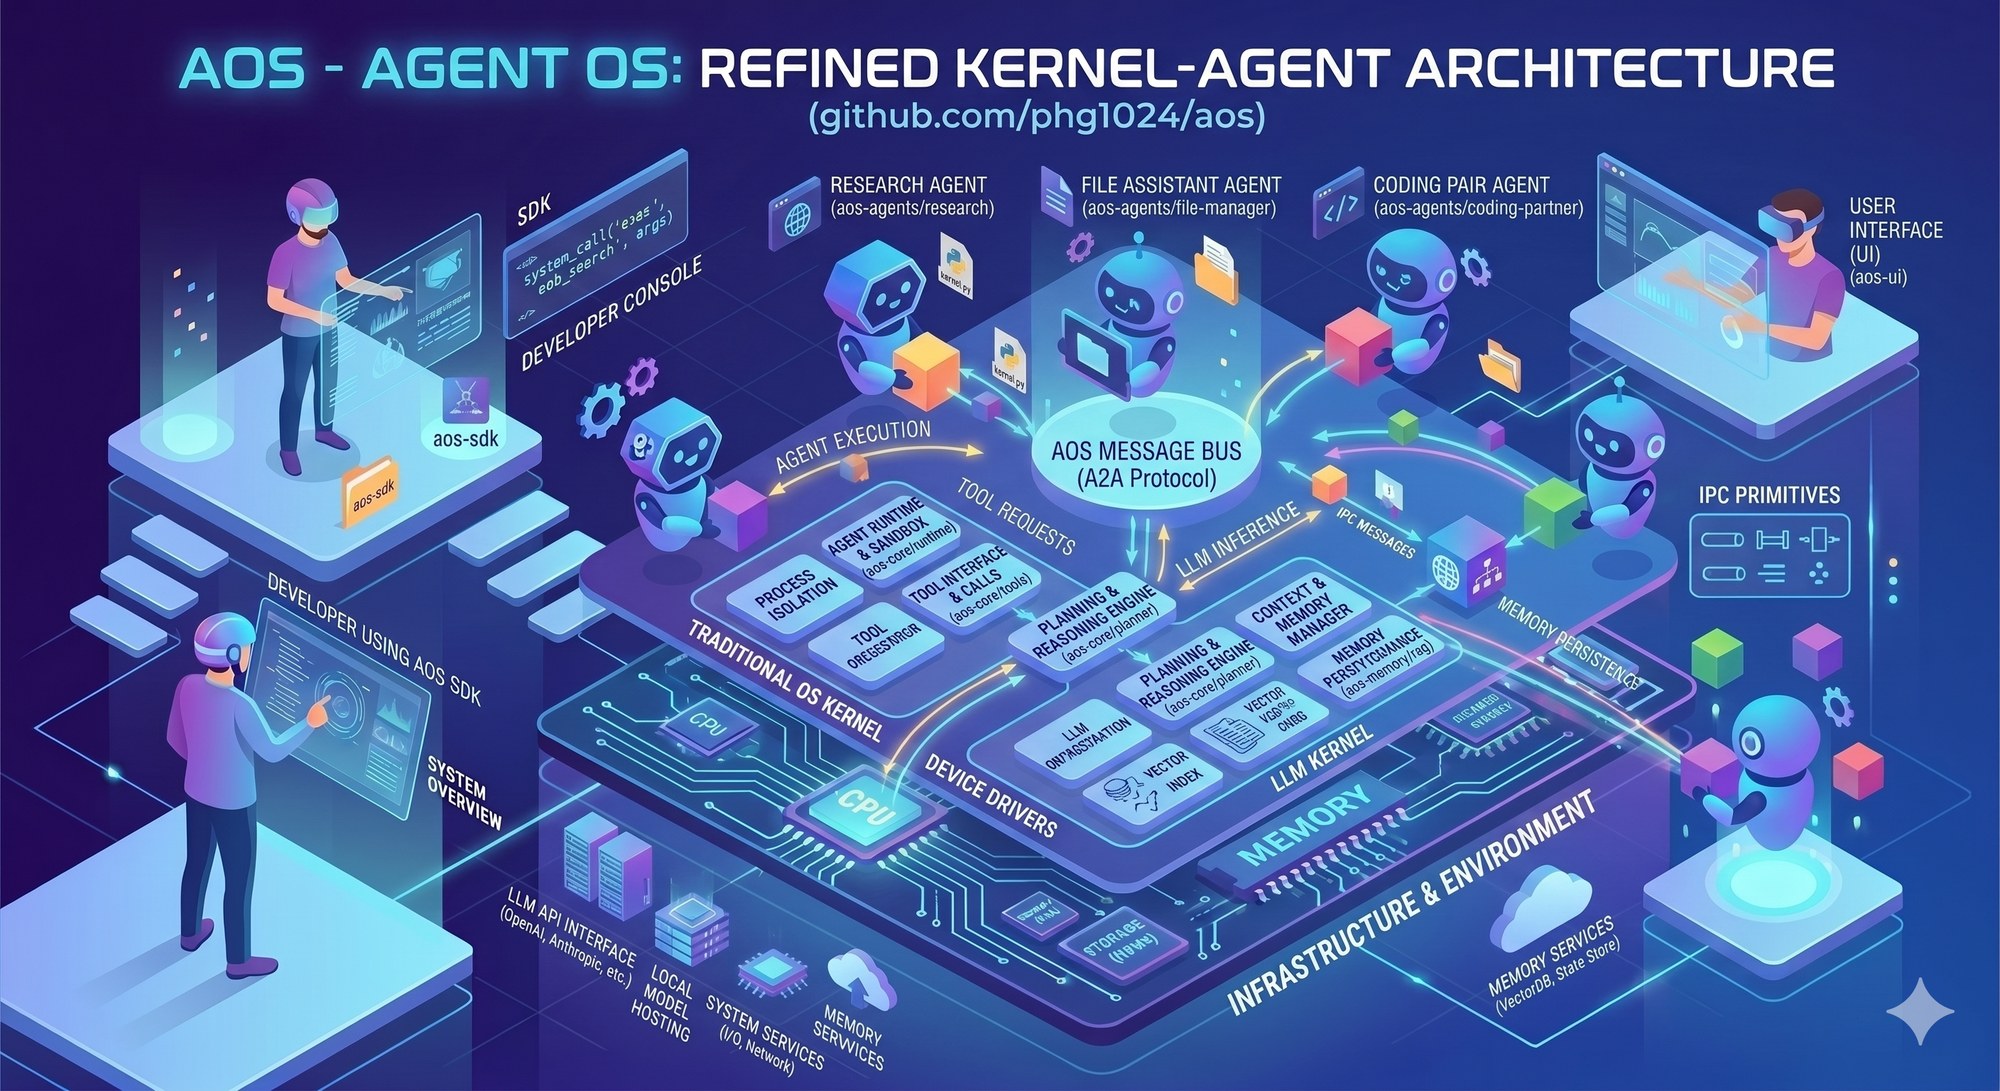
AOS: Agent Operating System
A research prototype for agent collaboration through runtime primitives: artifacts, messaging, capabilities, and scheduling.
-
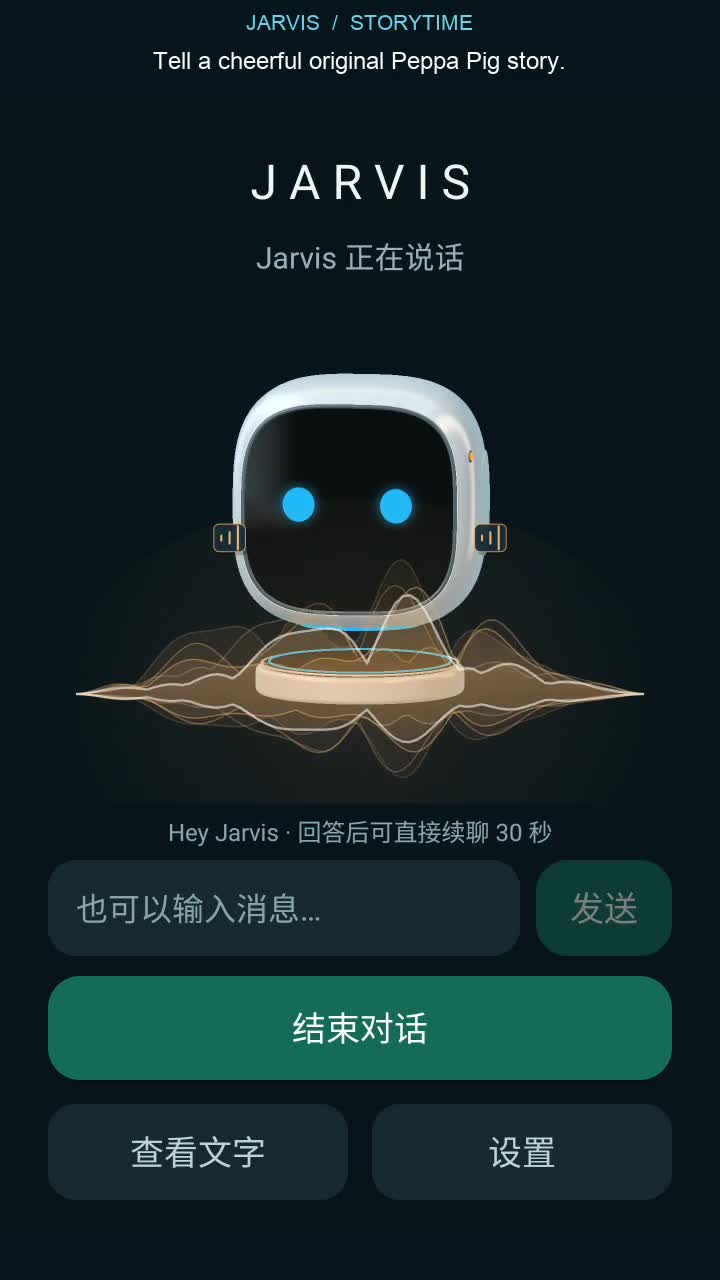
Jarvis Voice Assistant
An Android voice assistant with local Qwen inference, speech models, home-control tools, and a background update pipeline.
-
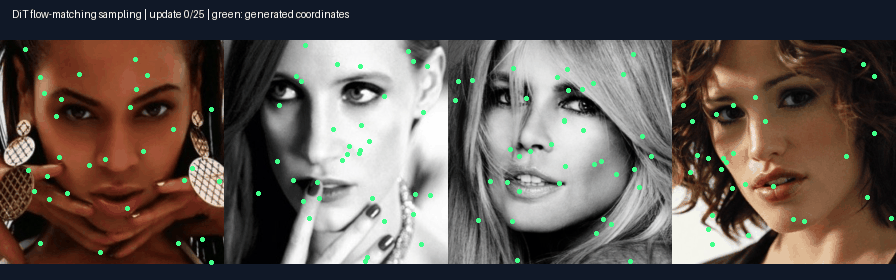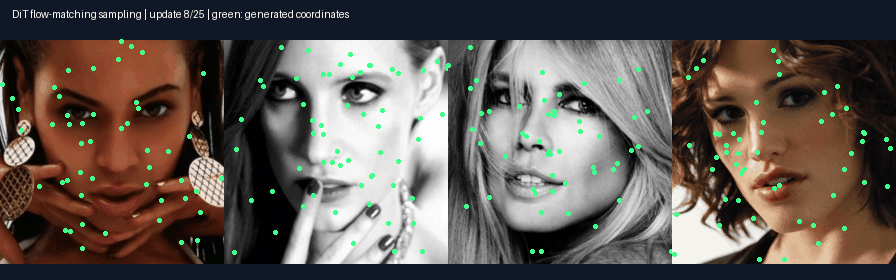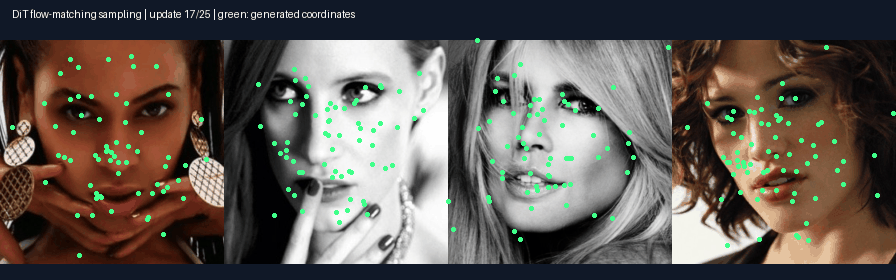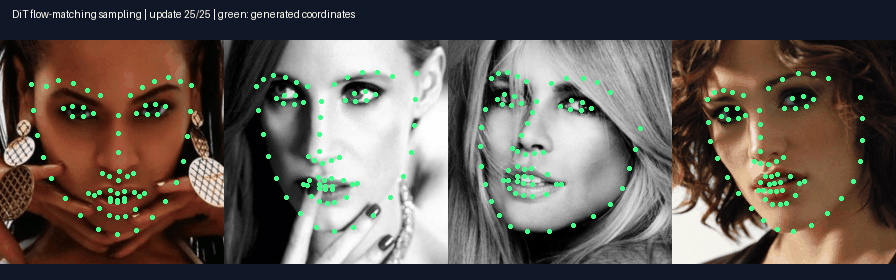
Generative Facial Keypoints
Exploring image-conditioned diffusion and flow matching for facial landmarks with frozen DINO features and transformer coordinate models.
-
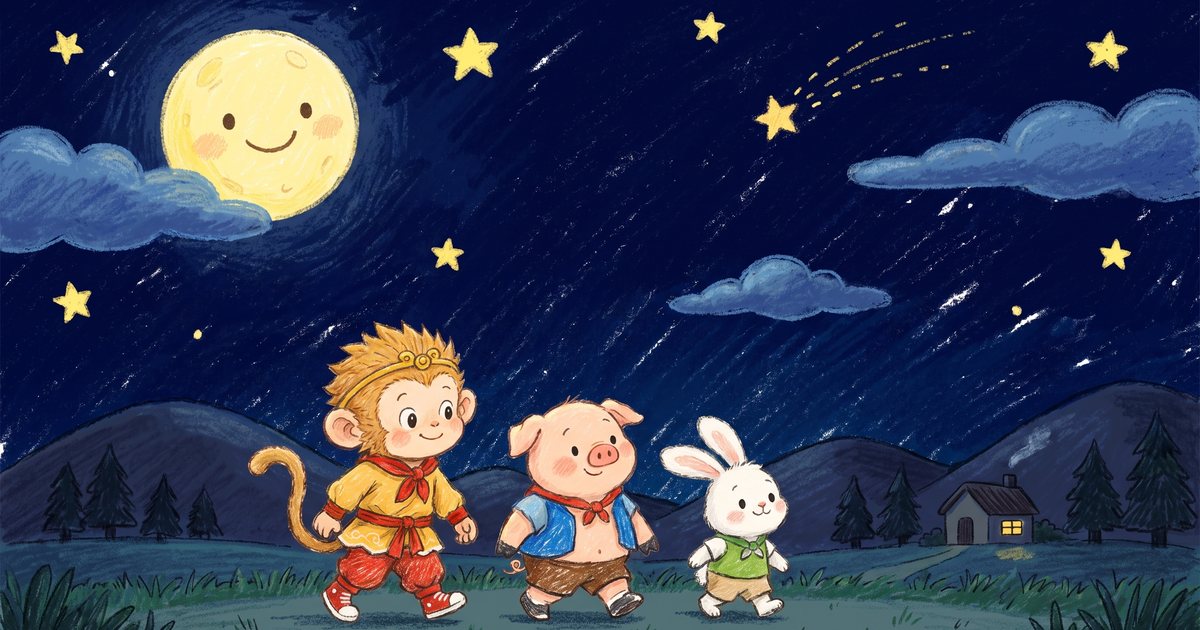
Wukong & Friends
Crayon-doodle bedtime picture books for young readers, with free reading and two-up booklet PDFs, published from a private repository against an Ed25519-signed manifest.
-
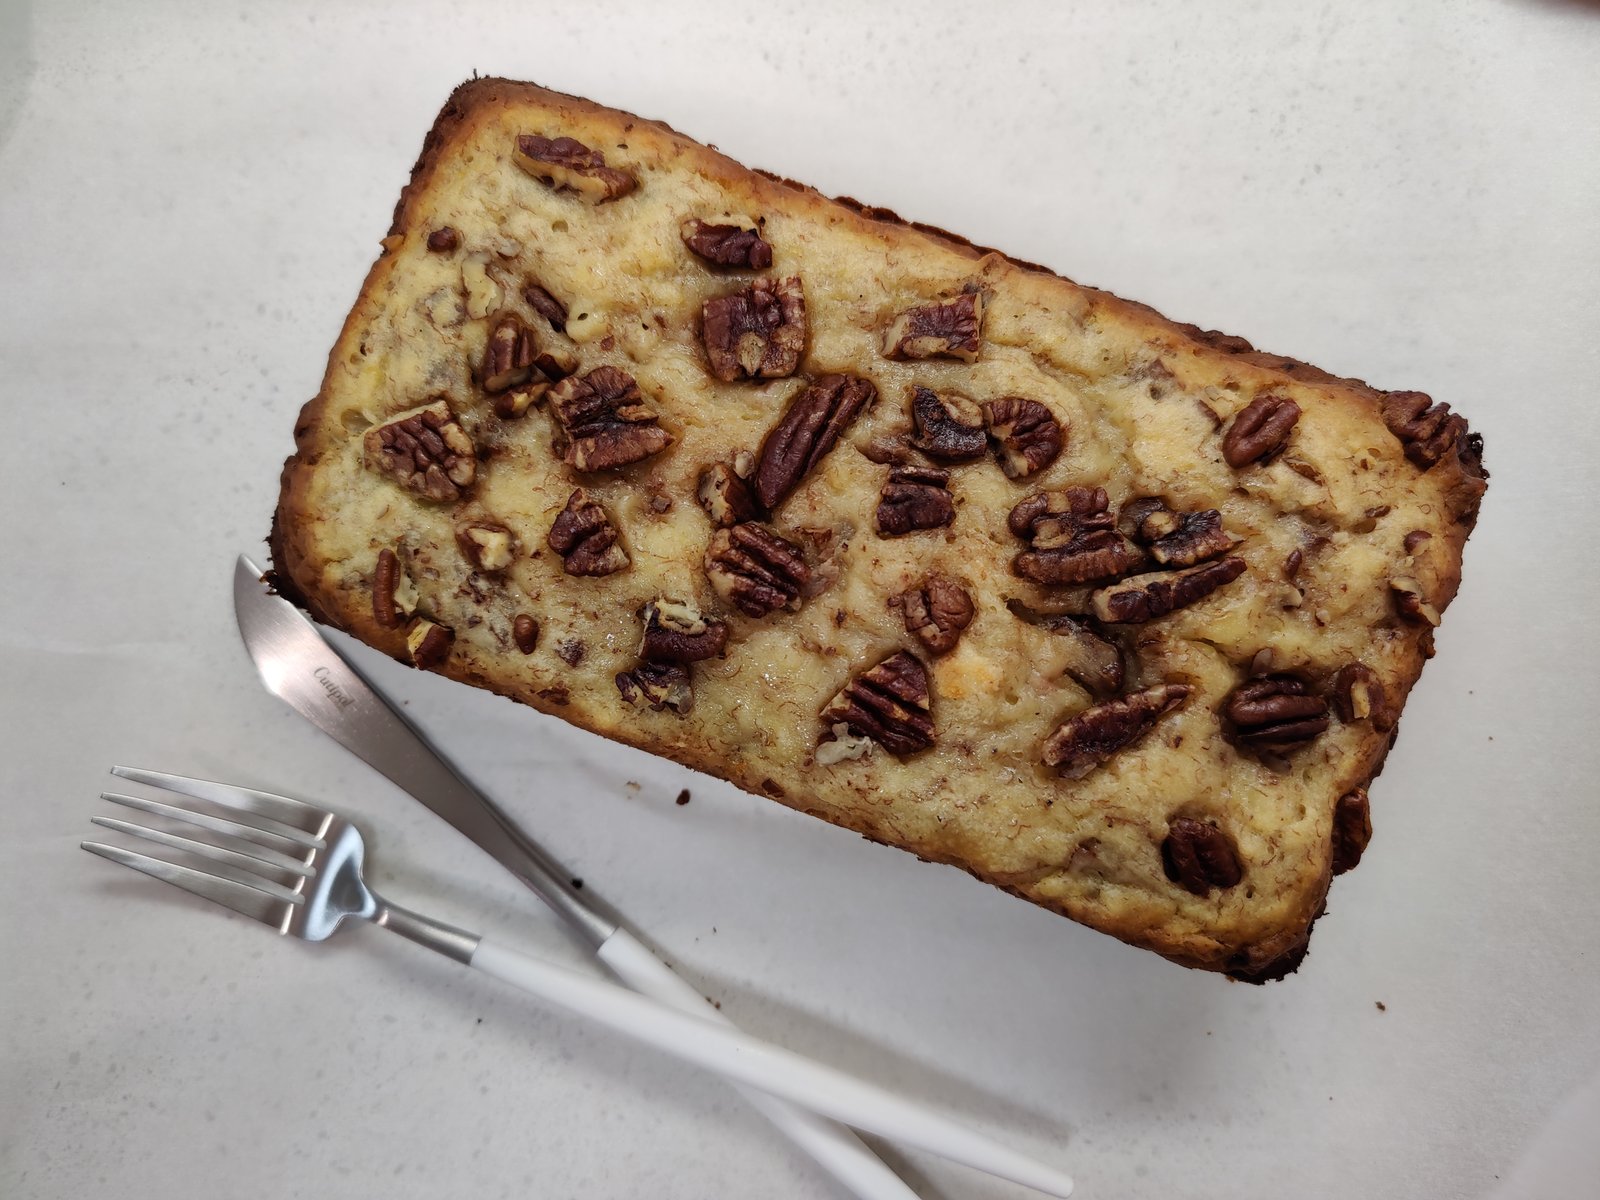
Bread
Six loaves, from a basic white bread to rye: recipes with before-and-after photos, in the order they were baked.
Also runs in your browser: Ray tracer · ImageProcJS · Fractal explorer · MineSweeper · Multilinear Reconstruction